
System Design Interview Preparation: A 4-Week Plan (With Practice)
Prepare for system design interviews in four weeks: building blocks, scaling and estimation, eight classic designs and timed mock interviews.
You can prepare for a system design interview in four weeks: learn the building blocks in week 1 (load balancers, caching, databases, replication), the scaling patterns and estimation in week 2, six classic designs in week 3, and mock interviews in week 4. In every answer, follow the same four steps: clarify requirements, sketch a high-level design, go deep on the core components, then scale it.
This plan is written for engineers with a couple of years of experience heading into SDE-2, senior or backend rounds, and it works for freshers who want the basics. It includes a time budget for a 45-minute round, a week-by-week schedule, the estimation numbers you'll use most, eight practice problems with an Indian twist, and the mistakes that cost candidates the round. If you also want live help on system design and coding rounds, our guide to an AI assistant for system design and coding interviews covers what to test.
The four-step framework for every design question
The System Design Primer, one of the most-starred open resources on the topic (over 370,000 stars on GitHub), recommends the same four steps for any interview question. The structure matters because it shows how you'd handle an unclear problem at work, which is what the round is really testing.
| Step | What you do | Time in a 45-minute round |
|---|---|---|
| 1. Use cases, constraints, assumptions | Ask who the users are, the main features, scale (daily users, reads vs writes), latency and availability needs. Write them down. | 5–8 min |
| 2. High-level design | Draw the main components (clients, API layer, services, databases, caches, queues) and how requests flow. | 8–10 min |
| 3. Core components | Pick the one or two hardest parts and go deep: data model, APIs, key algorithms, consistency choices. | 15–18 min |
| 4. Scale the design | Find bottlenecks and fix them with caching, sharding, replication, queues and CDNs. Discuss failure cases. | 8–10 min |
Leave two or three minutes at the end to summarise the trade-offs you made. A short summary ties the design together and shows you know where its weak points are.
Week-by-week preparation plan
| Week | Focus | Topics | Output by the end of the week |
|---|---|---|---|
| 1 | Building blocks | Client-server, DNS, load balancers (layer 4 vs layer 7), reverse proxies, SQL vs NoSQL, indexes, replication, caching (cache-aside, write-through, write-behind) | One page of notes per topic, written in your own words |
| 2 | Scale and trade-offs | Sharding, partitioning keys, CAP theorem, consistency patterns, message queues, CDNs, rate limiting, back-of-the-envelope estimation, SLIs and SLOs | Estimation sheet you can do from memory; a list of trade-offs per component |
| 3 | Classic designs | Six designs from the practice list below, one per day, plus a review day | A diagram and a one-page write-up for each design |
| 4 | Mocks and your own systems | Three timed mock interviews, a deep review of one system you built at work or college, behavioural stories about design decisions | Recordings of mocks, a list of your weak spots, fixed |
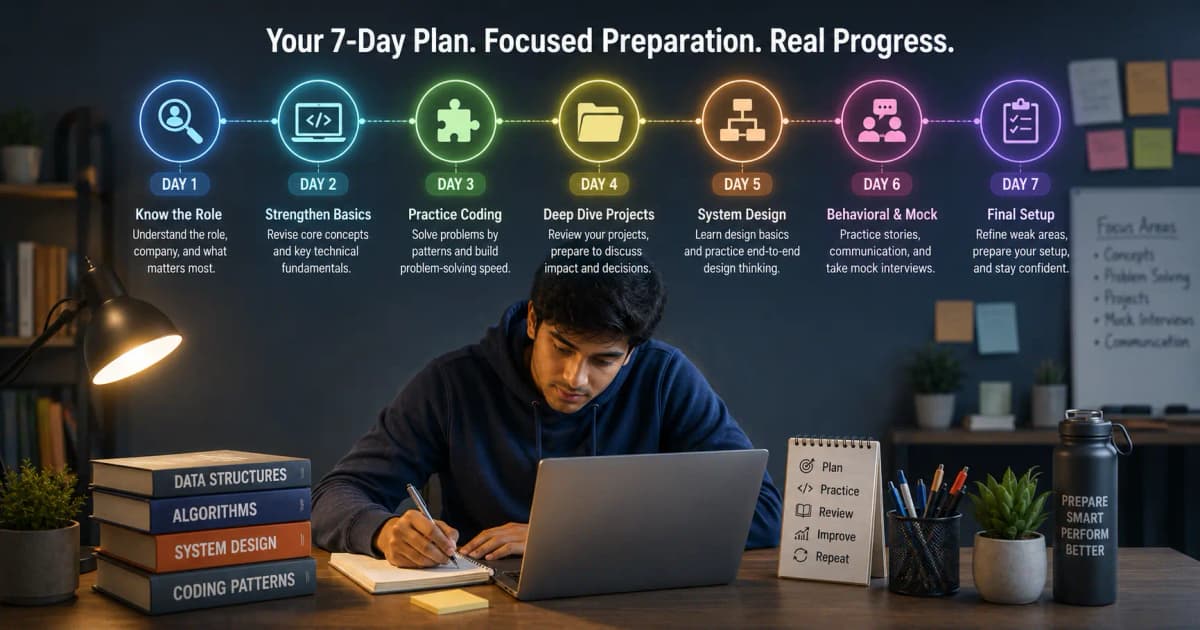
Plan about 90 minutes on weekdays and three hours on weekends. If you also have coding rounds, keep 30 minutes a day for them; our seven-day technical interview plan covers that side.
Requirements: say the numbers out loud
Strong candidates turn vague requirements into numbers early. Google's SRE book gives the vocabulary: a service level indicator (SLI) is "a carefully defined quantitative measure of some aspect of the level of service that is provided", and a service level objective (SLO) is "a target value or range of values for a service level that is measured by an SLI". Saying "p99 read latency under 200 ms, 99.9% availability" makes the rest of the design easier to justify. The same chapter explains why percentiles beat averages: an average hides the slow tail of requests that users actually notice.
For the non-functional side, AWS's Well-Architected Framework is a handy checklist. Its six pillars are operational excellence, security, reliability, performance efficiency, cost optimisation and sustainability. Mentioning cost and operations, not just performance, sets you apart in senior rounds.
Back-of-the-envelope numbers to know
You don't need exact figures, just quick, defendable estimates. These are plain arithmetic you can do in your head.
| Quantity | Rough value | Use it for |
|---|---|---|
| Seconds in a day | 86,400 (round to 100,000) | Converting daily volume to per-second rates |
| 1 million requests a day | About 12 requests per second on average | Average load |
| Peak load | Assume 2–5× the average, and say why | Capacity planning |
| 100 million records × 1 KB | About 100 GB | Storage size |
| Read-heavy ratio | Assume a ratio such as 10:1 reads to writes for feeds and catalogues, and say so | Deciding where to cache |
| Five years of data | Daily data × about 1,800 days | Long-term storage and sharding |
Write each assumption on the whiteboard. If the interviewer changes one, you can update the numbers in seconds instead of starting over.
Eight practice problems (with an Indian twist)
| Problem | What it tests | Key decisions |
|---|---|---|
| URL shortener | Basics, ID generation, caching | ID scheme (hash vs counter), redirect latency, analytics |
| Rate limiter for a public API | Algorithms, distributed counters | Token bucket vs sliding window, where the limiter sits |
| Chat app like WhatsApp | Real-time delivery, storage | WebSockets, message ordering, delivery receipts, offline users |
| News feed | Fan-out, ranking, caching | Fan-out on write vs read, celebrity accounts |
| Notification service (SMS, email, push) | Queues, retries, third-party providers | Priorities, idempotency, provider failover |
| Ride-hailing like Ola or Uber | Geo-indexing, matching | Location updates, geohash or quadtree, surge pricing |
| UPI-style payment flow | Consistency, idempotency, failure handling | Exactly-once effects, reconciliation, timeouts with banks |
| Live cricket streaming at peak | CDN, adaptive bitrate, spikes | Pre-scaling, edge caching, handling millions joining at once |
For each one, write a one-page answer: requirements with numbers, the diagram, the data model, the two hardest decisions and how it fails. Then explain it aloud to a friend in 20 minutes.
Mistakes that cost candidates the round
| Mistake | Better |
|---|---|
| Drawing boxes before asking any questions | Spend the first five minutes on requirements and numbers |
| Naming technologies without reasons ("use Kafka") | Say what problem it solves and what it costs |
| Designing for a billion users when the brief says a million | Design for the stated scale, then explain how you'd grow |
| Ignoring failure | Ask "what happens if this service or region goes down?" |
| Silence while thinking | Think aloud; the interviewer grades your reasoning |
| Running out of time in step 3 | Keep an eye on the clock and save time for scaling and trade-offs |
Practise with feedback
Mock interviews are where most of the improvement happens. Practise with a friend or a senior colleague who plays the interviewer and changes a requirement halfway through. Record the session and watch it once, noting where you went quiet or skipped requirements.
InterviewGPT can help with solo practice: it transcribes your mock session, can read the diagram or problem on your screen, and suggests a structured approach with trade-offs, so you can compare your answer with a cleaner version. Our guide to InterviewGPT for technical interviews shows the workflow, and the screen vision guide explains how diagrams are read. Use it where AI help is permitted. Download InterviewGPT for Windows and try a mock design round in a free 10-minute session.